FORKOFF Answer Engine Optimization is a structured-content and citation-routing service that earns tech, SaaS, deep tech and Web3/AI founders the named snippet inside ChatGPT, Perplexity, Bing Copilot, and Google AI Overviews. Schema, canonical Q&A, llms.txt, and parasite ladder decide which brand each engine selects when buyers ask.
Answer engine optimization (AEO) is the practice of structuring your content so AI answer engines like ChatGPT, Perplexity, Bing Copilot, and Google AI Overviews cite your brand inside the short answer they surface to a buyer. Where SEO competes for a blue-link rank, AEO competes for the four to eight brands an engine names when a buyer asks an evaluation question.
As Featured In
Full press shelf
AEO is a discovery reallocation, not a tactic. Every figure below is a published benchmark with a named source and a checkable link. The full method is in the answer engine optimization playbook.
Gartner projected that traditional search volume will fall 25% by 2026 as buyers move to AI chatbots and answer engines. (Gartner, 2024)
Only 38% of AI Overview citations now come from a Google top-10 page, down from 76%, so ranking first no longer earns the citation. (Ahrefs, 2026)
Adding cited statistics to a page lifts its visibility in generative-engine answers by 41%, authoritative-source citations by 115%, and expert quotations by 28%. (Princeton GEO study, 2024)
Brands in the top web-mention quartile earn 10x more AI Overview mentions than the next quartile. (Ahrefs, 2025)
Google users click a traditional result only 8% of the time when an AI summary appears, versus 15% of the time without one. (Pew Research, 2025)
FORKOFF has processed more than 5 billion qualified views across its clipping network, the proof base behind the weekly citation-share reporting on every AEO engagement. (FORKOFF, 2026)
Five patterns we see when a brand tries to get cited by answer engines and the work stalls inside the first quarter. Each row is the FORKOFF fix. Read it before you apply for the engagement.
Buyer asks ChatGPT, Claude, Perplexity, or Bing Copilot "what is the best X for Y" and the structured-answer block surfaces 4 to 8 cited brands. Brand never appears. Engines default to whichever competitor seeded the canonical answer first; brand becomes invisible to the high-intent comparison query the entire purchase decision turns on.
Quarterly canonical Q&A refresh on commercial pages with answer-first openers (1 to 2 sentence resolution under every H2). Listicle pages on the priority comparison queries with the brand self-listed. Parasite-ladder seeding (Medium, dev.to, HackerNoon, Substack) for cross-domain citation authority. Engines start citing brand within 30 to 60 days on Stage 1 to Stage 2 buyer journeys.
Brand surfaces in the structured-answer block but always at position 4 to 8 (alternative tier), never at position 1 to 2 (recommended tier). The buyer reads the recommended tier, picks one of those 2, and brand never enters the consideration set. Citation count goes up but pipeline stays flat because position determines conversion.
Position-engineering work distinct from coverage work. Authority signals stacked: Wikipedia disambiguation (engines weight Wikipedia heavily for recommended-tier ranking), G2 + Capterra + Clutch directory presence at high category rank, Hacker News and Reddit social co-signal on the priority query, original-data publication that engines cite as primary source. Position lift typically lands at 60 to 90 days.
Engines parse FAQ schema, Article schema, HowTo schema, Service schema, and Organization schema differently to assemble the structured answer. Wrong schema on the wrong page (FAQ schema on a service page, Service schema on a blog post) makes the canonical unit invisible. Schema validation against Google Rich Results passes but the engines downgrade or skip the unit at retrieval.
Schema graph audited against Google Rich Results, Bing structured data, Schema.org validators, AND per-engine retrieval test on the priority query bench. FAQ + Article + HowTo + Service + Organization shipped where each one earns retrieval weight. Schema regression check on every deploy; misuse blocks the build until corrected.
Crawlers from OpenAI (ChatGPT), Anthropic (Claude), Perplexity, and Microsoft (Bing Copilot) cannot find a curated index of brand canonical answers. Retrieval falls back to whatever the open web indexed years ago, which is rarely the freshest brand source. Brand canonical content might exist but never reaches the engine through the right crawl path.
llms.txt published with curated canonical units. Markdown content negotiation per route (agent crawlers resolve to clean per-page MD instead of the rendered React shell). Robots.txt agent rules tuned for the 4 priority answer-engine user-agents. Per-engine crawl log review weekly to catch crawl failures before they degrade citation.
Buyer-intent posts open with three paragraphs of preamble before resolving the question. Engines parse the page, find no liftable canonical sentence in the first 200 tokens under each H2, and skip the unit. Brand ranks on Google but stays invisible inside the structured-answer block on every priority query.
Answer-first rewrite on every commercial page. First sentence under each H2 resolves the question in 1 to 2 sentences. Liftable as a snippet with no edit. Engine repeats the canonical sentence the brand controls instead of paraphrasing a third-party article that buried the brand. Citation lift typically lands inside 30 days for Stage 1 to Stage 2 brands.
Traditional SEO competes for a Google rank that buyers increasingly skip. AI content shops ship more prose into a corpus engines never retrieve. FORKOFF engineers the structured unit, schema, and citation surface the four engines actually repeat. This one engagement runs all three AI-search facets, answer engine optimization for the cited list, generative engine optimization for the synthesized paragraph, and LLM SEO for the source corpus, covered in the answer capsules below. When Perplexity dominates the buyer ICP, sharpen with a Perplexity SEO deep-dive. The retrieval mechanics behind it are in how AI Overviews rank brands.
Three engagements across AI infra, B2B SaaS, and a Web3 protocol. Retainers that rewired the schema graph, grounded the entity in Wikidata, shipped the parasite ladder, and reported a weekly proof the founder could read in two minutes. The same engagement covers AEO citation work, GEO synthesis-quality work, and LLM SEO corpus grounding, then sharpens on a single engine with a Perplexity SEO deep-dive when the buyer ICP demands it.
Cited-share lift across a 60-day AEO sprint on an AI infra brand. Stage 1 to Stage 4 across 4 engines.
Days from kickoff to first answer-engine citation lift on Stage 1 to Stage 2 brands.
Citation-lift turnaround. First measurable answer-engine citation improvement within two weeks of corpus deployment.
You keep the schema graph, llms.txt, parasite content, and citation ledger.
The qualification ledger changed how we report to the board. Real attention, verified weekly, not dashboard vanity.
Alex Morgan
Growth Lead, AI Infrastructure Startup
Most teams bolt on AI visibility as an afterthought inside a broader content retainer. FORKOFF is built around it.
When buyers ask ChatGPT, Perplexity, or Bing Copilot which vendor to use, Google rank no longer decides who gets cited. The AI SEO agency you hire needs to understand structured-answer engineering, not just blue-link keyword targeting. FORKOFF is that agency: every engagement is measured across the 4 answer engines we track, ChatGPT, Perplexity, Bing Copilot and Google AI Overviews, and covers citation engineering, corpus grounding via LLM SEO, and synthesis quality via GEO, operated as one system with a weekly proof.
Before a retainer starts you can buy the diagnosis on its own. Our Pre-AI Readiness audit scores 5 readiness points by hand rather than by crawler, and we deliver it in 5 business days, with the fee credited toward the retainer if you move into one.
Our AI SEO services consolidate what most shops sell as three separate retainers: AEO for structured-answer citation, GEO for the synthesized paragraph the engine writes mid-answer, and LLM SEO for the upstream corpus signals that determine which brands an engine even considers. If you are still mapping the difference between AEO and GEO, the guide breaks down which surface each one wins. The full method runs end to end in the answer engine optimization guide, AEO for B2B SaaS covers the developer-tool ICP, and how the top AEO agencies compare shows how to vet one before you sign. You get one engagement, one outcome-priced contract, and one audit proof signed every Tuesday. Start with the AEO citation diagnostic to map where your brand stands across the full AI search stack before committing to a retainer.
Not a rebranded SEO retainer. GEO services engineer the synthesized paragraph and the cited list AI answer engines write for a buyer, then prove it with a weekly citation scan.
GEO services are the generative engine optimization work an agency runs to control how AI answer surfaces cite and describe your brand: entity grounding, schema, canonical answer blocks, original data, and a weekly citation proof across ChatGPT, Perplexity, Bing Copilot, and Google AI Overviews.
A generative engine optimization agency works the surface a blue-link rank no longer decides. GEO services shape the synthesized paragraph an engine writes mid-answer and the four to eight brands it names as recommended or alternative, which is where a growing share of buyer research now starts. FORKOFF runs GEO services, AEO services, and LLM SEO as one outcome-priced engagement, so corpus grounding, synthesis quality, and citation position compound instead of billing as three separate retainers. If you are weighing a dedicated GEO agency against a broader AI search retainer, the split between the surfaces is mapped in the AEO vs GEO guide.
AEO services and GEO services sit on the same infrastructure. AEO services engineer the cited list; GEO services engineer the synthesized paragraph; LLM SEO seeds the source corpus upstream of both. You get one engagement, one weekly proof signed every Tuesday, and you keep the schema graph, llms.txt, and citation record. Start with the AEO diagnostic to see where your brand stands across the full stack before a retainer.
Why the answer-engine surface is worth engineering
Answer engine optimization (AEO) is the practice of structuring your content so AI answer engines like ChatGPT, Perplexity, Bing Copilot, and Google AI Overviews cite your brand inside the short answer they surface to a buyer.
Where classic SEO competes for a blue-link rank on Google, AEO competes for the 4 to 8 brands an engine names when a buyer asks a comparison or evaluation question. The levers are schema discipline, canonical Q&A blocks with answer-first openers, an llms.txt agent surface, and authority signals that decide whether you are cited as recommended or only as an alternative. FORKOFF runs AEO as an outcome-priced engagement measured on a weekly citation proof across four answer engines. What that costs, and why AEO is priced on outcomes rather than hours logged, is broken down in how much answer engine optimization costs.
AEO targets citation inside an AI-generated answer, while SEO targets rank on a list of blue links. A page can rank first on Google and still never appear in the ChatGPT or Perplexity answer the buyer reads instead, because an answer engine selects the passages it can quote and attribute rather than the pages it can order.
The two share a foundation, since both depend on a crawlable, indexable page, so AEO sits on top of SEO rather than replacing it. The split is the surface and the measurement. SEO is measured on rank and clicks; AEO is measured on citation share across answer engines, which no rank tracker reports. For the full side-by-side, read the AEO vs SEO difference guide.
Generative engine optimization (GEO) is the practice of shaping how generative AI surfaces like Google AI Overviews, Bing Copilot, ChatGPT search, and Perplexity Pro describe your category inside the synthesized paragraph they write for a buyer.
Where AEO works the cited list, GEO works the synthesis. The levers are entity grounding through Wikidata and Organization schema, original benchmarks the engine can attribute to your brand, and distilled subject-verb-object claims an engine can lift mid-paragraph. FORKOFF delivers GEO inside the same AI-search engagement as AEO, measured on weekly paragraph-pickup across four generative surfaces rather than blue-link rank. The line between the two surfaces is in the AEO vs GEO guide.
LLM SEO is corpus engineering: building your brand presence across the source surfaces large language models ground on, such as Wikipedia, Wikidata, GitHub, and arxiv, so the model knows your brand and can cite it.
It works upstream of citation. Where AEO shapes the structured answer an engine repeats and GEO shapes the synthesized paragraph, LLM SEO seeds the underlying source graph the model retrieves from in the first place, tracked on a source-diversity score across roughly twelve corpus surfaces. FORKOFF runs it as one facet of the AI-search retainer, so corpus grounding, synthesis quality, and citation position compound together instead of being sold as three separate engagements. The structured-data layer that makes a corpus machine-readable is covered in schema markup for AEO.
Three routes to answer-engine citation. Match the engagement to the surface you actually need ranked, the schema discipline you can sustain, and the weekly-proof cadence you want shipped weekly.
← scroll horizontally to see more →
| Feature | FORKOFF AEOCitation engineering · 4 answer engines · structured-answer position | Generic AI SEO shopMass content shipped · no structured-answer engineering | Other FORKOFF AI-search spokesLLM SEO (corpus) · ASO (portfolio) · GEO (synthesis) · Perplexity (4-mode) · AI SEO (hybrid) |
|---|---|---|---|
| Surface focus | The structured-answer block. The 4 to 8 brands cited as recommended or alternative when buyers ask comparison queries on ChatGPT, Claude, Perplexity, Bing Copilot | Whatever the engine does with mass-shipped content; no structured-answer engineering discipline | LLM SEO targets the corpus (upstream); GEO targets the synthesized paragraph; ASO targets portfolio breadth; Perplexity SEO single-engine deep; AI SEO Services hybrid SEO + AI-search |
| Engines covered | ChatGPT, Claude, Perplexity, Bing Copilot - the 4 answer engines that ship structured-answer blocks with citations | Google blue-link + ChatGPT only; Claude, Bing Copilot, Perplexity treated as out of scope | Sister spokes cover different engine sets (LLM SEO 4 LLMs, ASO 5 engines, GEO 4 generative surfaces, Perplexity-only) |
| Citation position vs coverage | Position-engineering: recommended tier (position 1-2) vs alternative tier (4-8). Authority + Wikipedia + directory rank determine position | Coverage-only; brand cited as alternative permanently with no position-lift work | Sister spokes optimize for different KPIs (corpus diversity, paragraph pickup, portfolio balance, mode coverage) |
| Schema discipline | FAQ + Article + HowTo + Service + Org graph audited against Google Rich Results AND per-engine retrieval test | Generic schema validation; per-engine retrieval test never run | Sister spokes use schema as one signal among many; AEO is most schema-discipline-heavy |
| When to choose this | Buyer journey runs through the structured-answer block on the 4 answer engines (most B2B comparison and evaluation queries) | Brand needs Google blue-link traffic only; AI-search out of scope | Brand needs corpus seeding (LLM SEO), portfolio breadth (ASO), synthesis quality (GEO), Perplexity depth (Perplexity SEO), or hybrid Google + AI-search (AI SEO Services) |
| Pricing model | Sandbox audit · retainer by application · outcome-priced milestones | Hourly retainer regardless of result | Each sister spoke at the same sandbox audit · retainer by application |
20 to 40 commercial queries, 4 answer engines (ChatGPT, Perplexity, Bing Copilot, Google AI Overviews), one structured-answer map. You get the gap diagnosis, schema audit, and Q&A engineering plan in 5 business days. If FORKOFF cannot find actionable AEO gaps, the fee gets refunded. Retainer is monthly, pricing by application, after the audit lands.
Submit a URL and the AEO checker reports schema coverage, answer-capsule presence, entity authority, and citation density the way ChatGPT, Perplexity, Claude, and Google AI Overviews read it. The scan runs in the browser with no registration.
Want a human read instead of an automated score? The paid Pre-AI Readiness 5-Point Audit scores your whole site by hand across five dimensions and four answer engines, then hands you a ranked fix list. It is the done-for-you step between the free checker and a full retainer. The AEO checker above audits the HTML signal on a single page. To see whether ChatGPT, Perplexity, and Claude actually cite your brand today, run the free AI Search Visibility Checker for the citation read, and the GEO audit for the agent-readiness substrate underneath both.
AEO (Answer Engine Optimization) is the citation-engineering layer that decides which brands ChatGPT, Claude, Perplexity, and Bing Copilot cite in their structured-answer block. Where SEO competes for Google blue-link rank, AEO competes for the 4 to 8 brands an answer engine cites as recommended or alternative on a buyer comparison query. The two share infrastructure (clean schema helps both) but a brand can rank #1 on Google and stay invisible inside ChatGPT, Claude, Perplexity, or Bing Copilot at retrieval.
They are three facets of one AI-search engagement, not three separate retainers. AEO (answer engine optimization) is citation engineering: which brands ChatGPT, Claude, Perplexity, and Bing Copilot name in the structured-answer block. GEO (generative engine optimization) is synthesis-quality work: shaping the paragraph Google AI Overviews and Bing Copilot write mid-answer, through Wikidata entity grounding and original benchmarks. LLM SEO is corpus engineering upstream of both: building brand presence across the source surfaces models ground on, such as Wikipedia, Wikidata, GitHub, and arxiv, so the model knows the brand before it can cite it. FORKOFF runs all three in one outcome-priced engagement with a weekly citation proof. Perplexity SEO stays a distinct single-engine deep-dive when Perplexity dominates the buyer ICP.
A generative engine optimization agency shapes how AI Overviews, Bing Copilot, ChatGPT search, and Perplexity Pro describe your category inside the synthesized paragraph they write for a buyer, rather than competing for a blue-link rank. The work is entity grounding through Wikidata and Organization schema, publishing original benchmarks the engine can attribute to your brand, and distilling category-defining claims into subject-verb-object sentences an engine can lift mid-paragraph. FORKOFF delivers GEO as part of the same AI-search engagement as AEO and LLM SEO, measured on weekly paragraph-pickup (does brand-distilled language appear in the synthesized answer) across four generative surfaces, which conventional citation tracking misses on 50 to 70% of synthesis-stage exposure.
GEO services (generative engine optimization services) include entity grounding through Wikidata and Organization schema, a schema graph audited against Google Rich Results, canonical answer blocks with answer-first openers, original data and benchmarks an engine can attribute to your brand, an llms.txt agent surface, and a weekly citation scan across ChatGPT, Perplexity, Bing Copilot, and Google AI Overviews. The target of GEO services is the synthesized paragraph and the cited list an engine writes for a buyer, not a blue-link rank. FORKOFF delivers GEO services inside the same engagement as AEO and LLM SEO, priced on outcomes with a weekly proof rather than hours logged.
AEO services engineer the cited list an answer engine surfaces (which four to eight brands ChatGPT, Claude, Perplexity, and Bing Copilot name as recommended or alternative), while GEO services engineer the synthesized paragraph the engine writes mid-answer. AEO services and GEO services share infrastructure, clean schema, canonical Q&A, and an llms.txt surface, and FORKOFF runs both plus LLM SEO corpus grounding as one AI search engagement. You do not buy them as three separate retainers; the weekly citation proof covers all three surfaces at once.
An LLM SEO agency engineers the corpus large language models ground on at training and retrieval time: Wikipedia, Wikidata, arxiv, GitHub, Stack Overflow, Reddit, Medium, dev.to, HackerNoon, Substack, and similar source surfaces. The corpus matters because a model cannot cite a brand it was never grounded on, so LLM SEO works upstream of both AEO citation and GEO synthesis. Without a Wikidata entity ID and diversified source presence, engines conflate the brand with adjacent competitors or paraphrase it out of the answer. FORKOFF tracks LLM SEO on a source-diversity score across roughly twelve corpus surfaces and runs it inside the one AI-search retainer so corpus grounding compounds with citation-position work.
Sandbox audit, 5 business days. 20 to 40 commercial query bench scanned across ChatGPT, Claude, Perplexity, and Bing Copilot. Citation count + position + context (recommended vs alternative vs absent) logged per query per engine. Schema graph audited against Google Rich Results + Bing structured data + Schema.org validators. llms.txt and agent-crawler audit. Position-lift forecast for the priority query set. Refund logic if no actionable AEO gaps surface.
30-day baseline citation lift for Stage 1 to Stage 2 brands (zero or near-zero starting citations) once answer-first rewrite + schema graph + llms.txt land. 60 to 90 days to engineer reliable structured-answer pickup on commercial queries. Position lift (alternative-to-recommended tier) takes 90 to 180 days because it requires authority work - Wikipedia, directory rank, social co-signal, original-data publication. Stage 5 (default-cited recommended on the priority query set) takes 6 to 12 months.
Citation count alone misses 50%+ of pipeline impact. The structured-answer block surfaces 4 to 8 brands; buyers read the top 1 to 2 (recommended tier) and pick from those. Position 4 to 8 is alternative-tier visibility, which gets cited but rarely converts. Position-engineering stacks Wikipedia disambiguation, directory rank (G2, Capterra, Clutch), social co-signal (Hacker News, Reddit), and original-data publication that engines cite as primary source. Authority signals compound to lift position from alternative to recommended over 60 to 180 days.
Updates shift patterns, not the work. GPT-4 Turbo to GPT-4o moved citation patterns roughly 20% across the FORKOFF roster, with one B2B SaaS brand recovering to prior position in 21 days after a re-engineered FAQ + comparison schema sweep. Anthropic Claude refresh in early 2026 was milder. The Monday scan flags drift inside a week and the re-engineering cycle ships inside 7 days. Built into the retainer cadence.
20 to 40 commercial queries × 4 answer engines × weekly Monday scan. Per-query: citation count, structured-answer position (recommended vs alternative vs absent), context (cited as best, cited as alternative, cited as competitor reference), and source-mix breakdown (which third-party domains cite the brand). Week-over-week delta math. Proof lands in founder inbox by Tuesday with operator signature. Quarterly scale call backed by per-query position trajectory.
No, and any agency selling that is selling snake oil. AEO is genuine schema engineering, canonical Q&A discipline, llms.txt curation, parasite-ladder authority work, and position-engineering through Wikipedia + directories + social co-signal + original data. Prompt-stuffing pages get filtered by safety classifiers and rarely surface at retrieval. The work compounds because it improves the canonical units the 4 answer engines actually retrieve and cite at structured-answer assembly time.
No. Answer engines do not have a single rank. Citations vary by query, prompt, model, context window, and engine refresh cadence. FORKOFF commits to measurable citation lift on a defined 20 to 40 query set with weekly qualified-view proof and 90-day position-trajectory reporting. Any agency promising #1 is lying. The honest commitment is the bench, the lift trajectory across recommended vs alternative tiers, and the weekly report.
Sandbox audit on entry, 5 business days, refund logic if no actionable gaps. Retainer by application after the audit, 90-day minimum, capped at 5 engagements per quarter, scaleable up or down at quarter end. The one engagement covers all three facets: AEO citation work, GEO synthesis-quality work when the buyer journey runs through synthesized paragraphs, and LLM SEO corpus grounding when the brand is missing from Wikidata, GitHub, or arxiv. Pair it with a Perplexity SEO deep-dive if Perplexity dominates the buyer ICP.
Start from the engines your buyers actually use, then judge an AEO agency on five things. One, does it run a real query bench (20 to 40 commercial queries scored across ChatGPT, Claude, Perplexity, and Bing Copilot) rather than a vibe check. Two, does it do genuine schema and canonical answer-block engineering, not prompt-stuffing. Three, does it report citation position (recommended vs alternative vs absent) every week, not just a citation count. Four, does it refuse to guarantee a number-one citation, because answer engines have no single rank. Five, does it show its own work with dated proof. An AEO agency that cannot answer those is selling SEO with a new label.
Ask for a sample query bench and a real read on one of your own commercial queries. Ask which third-party sources it engineers (Wikipedia, G2, Capterra, Reddit, original data), because position lift is authority work, not on-page tricks. Ask how it handles a model update: a credible AEO agency flags citation drift inside a week and re-engineers inside seven days. Walk away from anyone promising guaranteed number-one placement or selling AEO as adding prompts to your pages.
A traditional SEO agency competes for Google blue-link rank. An AEO agency competes for the four to eight brands an answer engine names in its structured-answer block when a buyer asks for a recommendation. The two share infrastructure (clean schema helps both), but the work diverges: an AEO agency engineers canonical answer blocks, llms.txt, citation position, and cross-engine coverage so ChatGPT, Claude, Perplexity, and Bing Copilot cite you, which a brand can lose even while ranking number one on Google.
Schema, canonical Q&A, entity grounding, llms.txt, and parasite ladder shipped in the first 30 days. Weekly Monday citation proof across 4 engines. Outcome-priced. Scaleable up or down at quarter end. One engagement covers answer engine optimization, generative engine optimization, and LLM SEO, then adds a Perplexity SEO deep-dive when a single engine wins your buyer.
Score any page's answer-engine readiness in seconds. The free companion to this service.
How FORKOFF compares to the field of answer-engine-optimization agencies. The buyer comparison.
6-dimension AI-native page audit: schema, snippet, citation surface, linking, answers, freshness.
Generate validator-ready, AEO-optimized Schema.org JSON-LD for any page type. Free tool.
The single-engine deep-dive when Perplexity dominates your buyer's research.
Which AI-search surface each facet wins, and when to lead with one over the other.
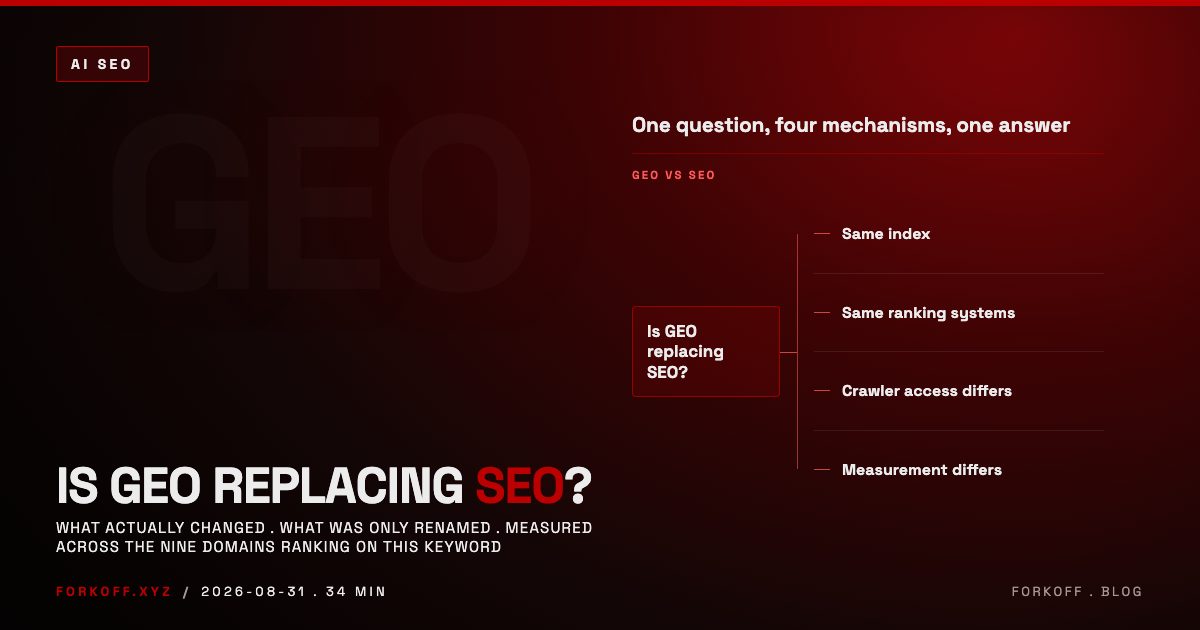
GEO is not replacing SEO. Here is what genuinely changed, what was only renamed, and measured crawler data on whether the two visibilities differ.
 Read
AI SEO agency vs AI SEO software, decided with real Reddit AMA retainer figures, published tool pricing, and a stage-by-stage framework.
Read
9 real AEO agencies for AI and SaaS startups: real disclosed pricing where it exists, platform coverage, and the checklist that spots a relabeled SEO shop.
Read