A ChatGPT citation strategy for agencies is a repeatable client engagement that measures how often a brand appears in the answers an AI assistant gives, then works to raise that rate. It runs as a loop rather than a campaign: audit prompt coverage against a locked set of buyer prompts, benchmark the client against named competitors, ship the on-page fixes, earn the third-party placements answer engines read, and report the movement each cycle. The metric the client buys is a citation rate, not a ranking, because a brand can sit at position one on Google and still be absent from the answer a buyer actually reads.
The 30-second answer to a ChatGPT citation strategy for agencies
A ChatGPT citation strategy for agencies is an operating loop, not a content tactic. The agency runs a prompt coverage audit of 30 to 60 prompts per topic cluster across ChatGPT, Perplexity, and Google AI Overviews, benchmarks the client against three named competitors on citation rate, mention rate, and share of voice, then ships the highest-leverage fixes: answer capsules, schema markup, a 90-day freshness cadence, and earned media placement. The monthly deliverable is a white-label PDF that ties citations to qualified lead lift. Around 72 percent of ChatGPT-cited pages carry an answer capsule, pages updated within 90 days draw roughly three times more citations than stale ones, and only 11 percent of cited domains overlap between ChatGPT and Perplexity, so agencies run two tracks, not one. FORKOFF runs this program for AI-native founders.
A client asks the question every agency now hears in the quarterly review: "Are we showing up in ChatGPT?" The honest answer, for most agencies, is a shrug. They have a rankings dashboard, a backlink report, and a content calendar. They do not have a number for how often the brand appears when a buyer asks an answer engine for a recommendation. That gap is the opening, and the agencies that close it are turning a one-line client question into a service line with its own audit, its own metrics, and its own monthly deliverable.
This is a playbook for building that service line. Not a brand-side explainer on getting your own company cited, and not a vendor pitch for a monitoring tool. It is the operating procedure an agency runs to scope, deliver, and report a ChatGPT citation program for a client, written for the person who has to package it, price it, and renew it. If you run answer engine optimization for clients, or you are about to, this is the workflow.
Most of the public material on this topic is written for the brand doing its own optimization, which is the wrong reader for an agency. A brand needs to know how to get itself cited. An agency needs to know how to run the same outcome as a repeatable, billable, reportable engagement across a portfolio of clients with different categories, different competitors, and different budgets. Those are different problems. The brand problem is a tactic. The agency problem is a system, and a system needs an audit it can repeat, a metric set it can report, a deliverable it can ship on a schedule, and a price it can defend. Everything below is built for the second problem.
About these numbers
Citation-signal statistics, all estimated operator figures (72% of cited pages carry an answer capsule, 3x freshness lift for pages updated within 90 days, 11% domain overlap between ChatGPT and Perplexity), are from FORKOFF agency field data and practitioner community observation; treat as directional operator estimates. The 30-to-60 prompt range and 180-to-300 weekly prompt target are practitioner standards from FORKOFF engagement methodology. Third-party citation figures (Princeton/academic GEO research at arxiv.org/abs/2311.09735) are sourced from the linked primary paper. Platform behavior descriptions (ChatGPT 2-4 sources, Perplexity 5-12) are from FORKOFF citation lab observation cross-referenced with linked platform documentation. Competitor pricing tool band estimates are from publicly listed pricing pages as of June 2026.
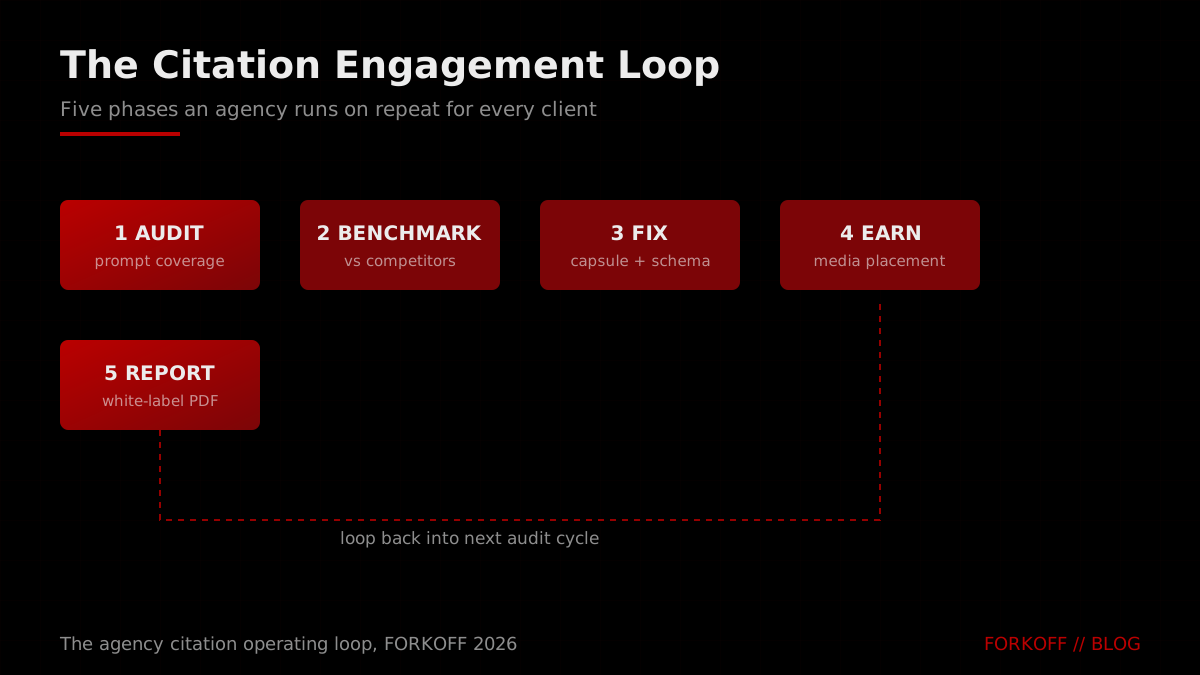
The shape of the work is a loop, not a campaign. You audit prompt coverage, benchmark the client against named competitors, ship the highest-leverage fixes, earn the placements that drive durable citations, and report the movement, then you start the next cycle. Each pass through the loop produces a deliverable, which is what keeps the engagement renewing. The rest of this guide walks each phase in the order an agency executes it.
Why ChatGPT citations became a client line item
The buyer behavior moved first, and the agency demand followed. Customers no longer scroll a page of blue links to decide what to buy. They ask an assistant, read the answer, and act on the recommendation. James Cadwallader, who builds in this category, frames the stakes in commercial terms rather than SEO ones.
James Cadwallader
thejamescad
Customers don't Google blue links to decide what to buy anymore. They ask ChatGPT. Google currently drives $2.4 trillion of commerce. In 5 years, $1 trillion of that will shift to ChatGPT. Becoming ChatGPT's #1 recommendation could be worth $100M+ to your business. Here's what… Show more
You do not have to accept the exact dollar projection to see the shift. The point that matters for an agency is structural: a brand can rank first on Google and still be absent from the answer a buyer reads inside ChatGPT. One SaaS operator described exactly that gap in a thread that agencies will recognize from their own accounts.
Client ranked top 3 on Google, completely invisible to ChatGPT
A SaaS operator reports a client holding top-3 Google rankings yet appearing in none of the ChatGPT answers buyers actually read, opening a thread on why classic rankings no longer guarantee answer-engine visibility.
That is the moment a citation program becomes sellable. The client has paid for rankings, the rankings are good, and the visibility that now matters is missing. In trust-heavy categories this is even more acute, because the query is often a safety check, which is why a fintech go-to-market playbook treats owning the AI answer to "is it safe" as a core acquisition move. An agency that can measure the gap, benchmark it against competitors, and present a plan to close it is selling a solution to a problem the client already feels. The agencies adding this to retainers in early 2026 report that clients understand it immediately once it is framed as AI share of voice.
Clients now ask about citations before they ask about rankings
The question has changed in the account meeting. A client used to ask where they rank for a head term. Now they ask whether they show up when a buyer asks ChatGPT for a recommendation. The agencies that answer that question with a number, a benchmark, and a plan win the retainer expansion. The ones that shrug lose the account to a competitor who built the citation report first. This is a service line, not a side project, and it carries its own audit, its own metrics, and its own monthly deliverable. The agencies adding it to retainers in 2026 are charging for the report, not absorbing the cost.
Source: FORKOFF field notes, 2026
What ChatGPT actually uses as a citation signal
Before you scope the work, you need a defensible model of what drives a citation. The research consensus, across academic work and practitioner experiments, points at a small set of signals. The University of Toronto generative engine optimization paper, summarized widely across the field, lands on a counterintuitive finding for anyone trained on classic SEO.
Alex Prompter
alex_prompter
🚨 The SEO playbook is dead. AI search engines like ChatGPT, Perplexity, Gemini aren’t ranking pages. They’re writing answers. The University of Toronto’s new paper “Generative Engine Optimization: How to Dominate AI Search” is the first real blueprint for this new reality. htt… Show more
The headline takeaway is that answer engines overwhelmingly prefer earned media, news, and expert sources over a brand's own blog or social posts. The original Princeton and academic GEO research quantifies how source structure and citation density shift what gets pulled into an answer. Layered on top, three signals show up again and again in agency field data.
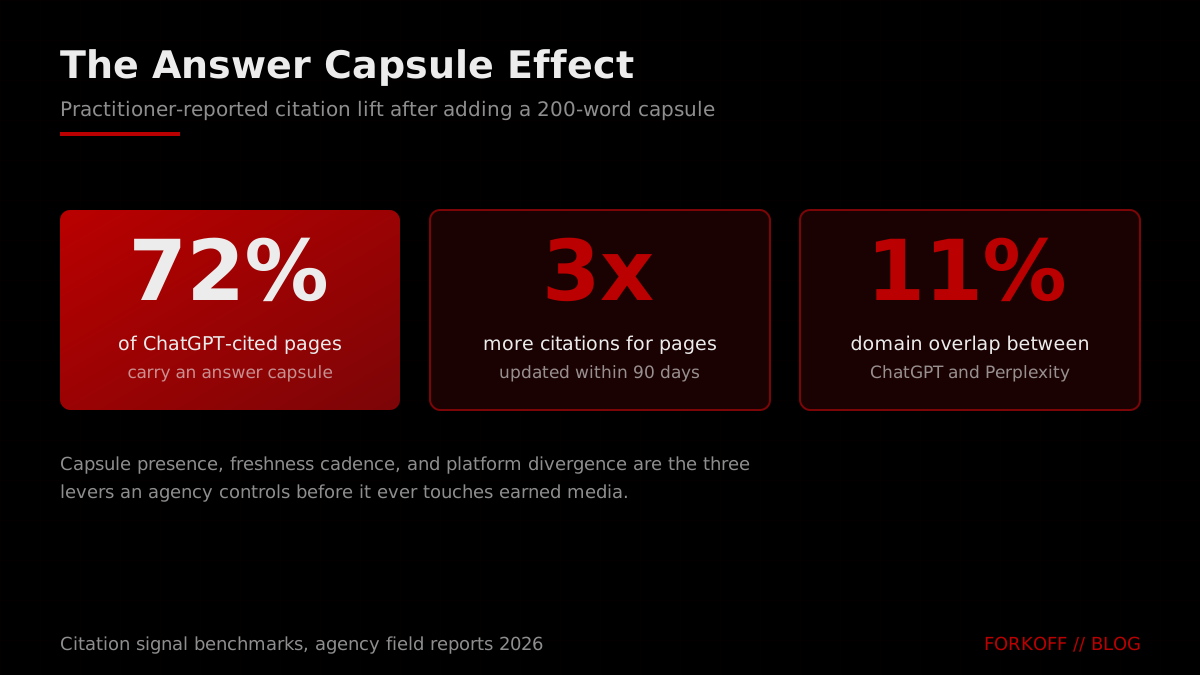
First, the answer capsule. Around 72 percent of ChatGPT-cited pages carry a two to three sentence direct answer placed in the first 200 words. The engine can lift that capsule verbatim, which makes it the single cheapest on-page fix an agency can ship. Second, freshness: pages updated within 90 days draw roughly three times more citations than stale ones, because engines weight recency. Third, the divergence between platforms, which we will come back to, because only about 11 percent of cited domains overlap between ChatGPT and Perplexity.
Authority sits underneath all three. Google's own guidance on helpful, people-first content describes the editorial signals that earn trust, and those signals carry into how answer engines weigh a source. One practitioner put the earned-media point bluntly in a thread that agencies should screenshot for client decks.
Engain
engain_io
88% of what ChatGPT cites doesn't rank on Google's first page. Your entire SEO strategy is built around Google rankings. But AI has its own system now. It rewards trust signals. Brand mentions by community discussion. Not backlinks. Not domain authority. Reddit is where ht… Show more
Earned coverage out-cites the client blog
The instinct is to publish more on the client domain. The data points the other way. AI engines weight earned media, community discussion, and independent review platforms above brand-owned pages when they assemble an answer. A well-structured blog post with an answer capsule earns the click once a buyer is already searching the brand. A placement in a publication the engine already trusts earns the citation that puts the brand in the answer before the buyer knows the brand exists. The agency budget that moves the needle splits across both, not all into owned content.
Source: University of Toronto GEO research, 2025
The platform signal stack: ChatGPT, Perplexity, and AI Overviews
The most expensive scoping mistake an agency makes is treating "AI search" as one surface. It is at least three, and they run on different plumbing. The single statistic that should reset the engagement plan is the 11 percent domain overlap between ChatGPT and Perplexity citations. If only one in nine cited domains is shared, a single content calendar cannot serve both engines.
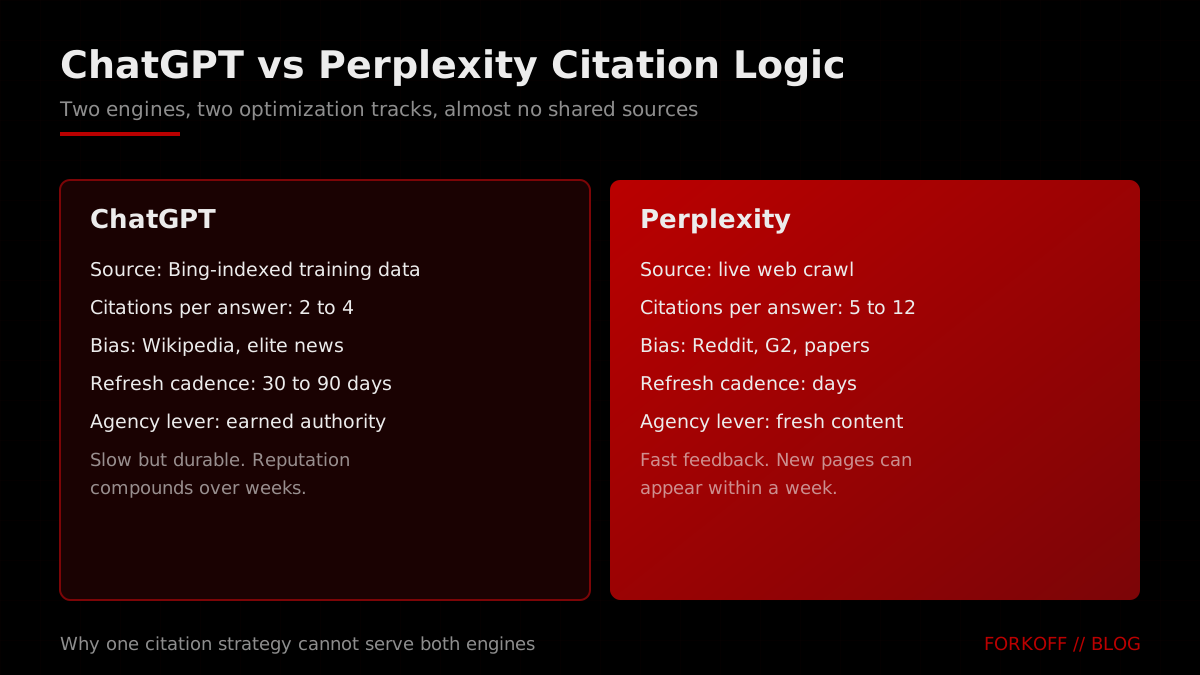
ChatGPT leans on Bing-indexed training data and tends to cite two to four sources per answer, biased toward reference works and established publications. OpenAI's own web search tooling documentation describes how the assistant retrieves and grounds answers in live sources on top of that training base. The agency lever for ChatGPT is earned authority that compounds slowly but durably. Perplexity crawls the live web and footnotes five to twelve sources per answer, favoring Reddit, review platforms, and papers, so the lever is fresh, structured content with fast feedback.
Google AI Overviews is the third surface, and it behaves more like classic search than either of the others. It draws on the Googlebot index plus structured data, which is documented in Google's AI features and your website guidance and its structured data reference for FAQ pages. Google's own announcement of AI Mode in Search signals how central the generative answer is becoming to the search product itself, which is the strongest argument an agency can hand a skeptical client. The lever there is schema, helpful content, and indexed authority, the same disciplines as technical SEO but pointed at a generative surface. Anthropic's citations documentation for Claude shows how a fourth engine grounds claims, which matters as soon as a client asks about Claude coverage too.
Perplexity is worth scoping explicitly because its live-crawl model rewards exactly the work that ChatGPT is slow to credit. (How Perplexity and Google AI Overviews differ in citation mechanics, and which to optimize first, is covered in detail in the Perplexity vs Google AI Overviews decision framework.) Perplexity's own developer documentation describes a system built around real-time retrieval, which is why fresh, well-structured content can surface there within days rather than waiting on a training cycle. For an agency, that makes Perplexity the fast-feedback engine: ship a capsule on Monday, check whether it moved a citation by the following week, and use that signal to validate the on-page approach before committing it across the slower ChatGPT track.
ChatGPT, Perplexity, and Google AI Overviews need separate tracks
| Platform | Primary source | Citations per answer | Agency lever |
|---|---|---|---|
| ChatGPT | Bing-indexed training data | 2 to 4 | Earned authority, durable over weeks |
| Perplexity | Live web crawl | 5 to 12 | Fresh, structured content, fast feedback |
| Google AI Overviews | Googlebot index plus structured data | Varies by query | Schema, helpful content, indexed authority |
One unified AI strategy is the most common scoping mistake
Agencies that treat ChatGPT and Perplexity as one optimization problem under-deliver on both. ChatGPT leans on Bing-indexed training data and cites a small set of high-trust sources, so the lever is earned authority that compounds over weeks. Perplexity crawls the live web and footnotes Reddit, review platforms, and papers, so the lever is fresh, structured content that can land within days. Scoping a single content calendar against both engines produces a deliverable that moves neither number. Split the tracks at the audit stage, report them separately, and the client sees exactly which engine the work is moving.
Source: FORKOFF citation lab observations, 2026
The practical consequence is that your audit, your content tracks, and your report all split by platform from the start. A marketer who tracked this divergence across their own brand described the realization that these are not the same optimization problem, and that conversation is playing out across agency accounts in real time.
Constructing the prompt set
The audit begins with prompts, and the prompt set is where most agencies under-invest. The working standard is 30 to 60 prompts per topic cluster, per platform. For a typical B2B client with three to five product categories, that lands at roughly 180 to 300 prompts per platform per week. The discipline is not volume for its own sake. It is coverage of the actual buyer journey.
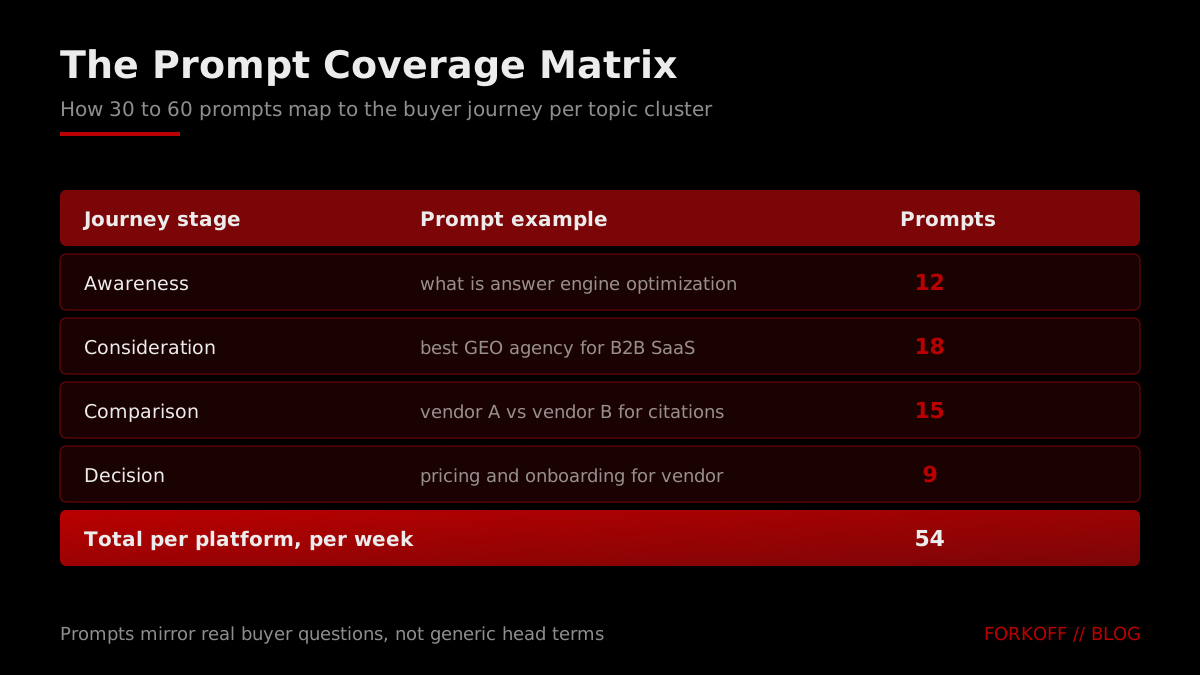
Write prompts that mirror the questions a buyer asks at each stage, not generic head terms. An awareness prompt asks what a category even is. A consideration prompt asks for the best option for a specific use case. A comparison prompt pits two named vendors against each other. A decision prompt asks about pricing and onboarding. Spread the set across those stages so the report can show the client where in the funnel they are cited and where they vanish.
Operator note54 prompts per platform per week is the working floor for a 3-cluster B2B client. Below 30 the sample is noise., FORKOFF citation audit cadence, 2026
Run the prompts at consistent times to control for recency bias, and keep the set stable week over week so the trend line is honest. When you add a prompt mid-quarter, mark it, because a citation-rate jump that is really a denominator change will get caught in the next client review and cost you trust. The AI search visibility checker is a fast first read on a single domain before you commit an account team to the full weekly set.
Building the client citation audit
With the prompt set running, the audit produces the baseline. For each prompt you record whether the brand was cited with a link, named without a link, or absent, and you do the same for the three named competitors the client cares about. That raw log rolls up into the three numbers that anchor every report.
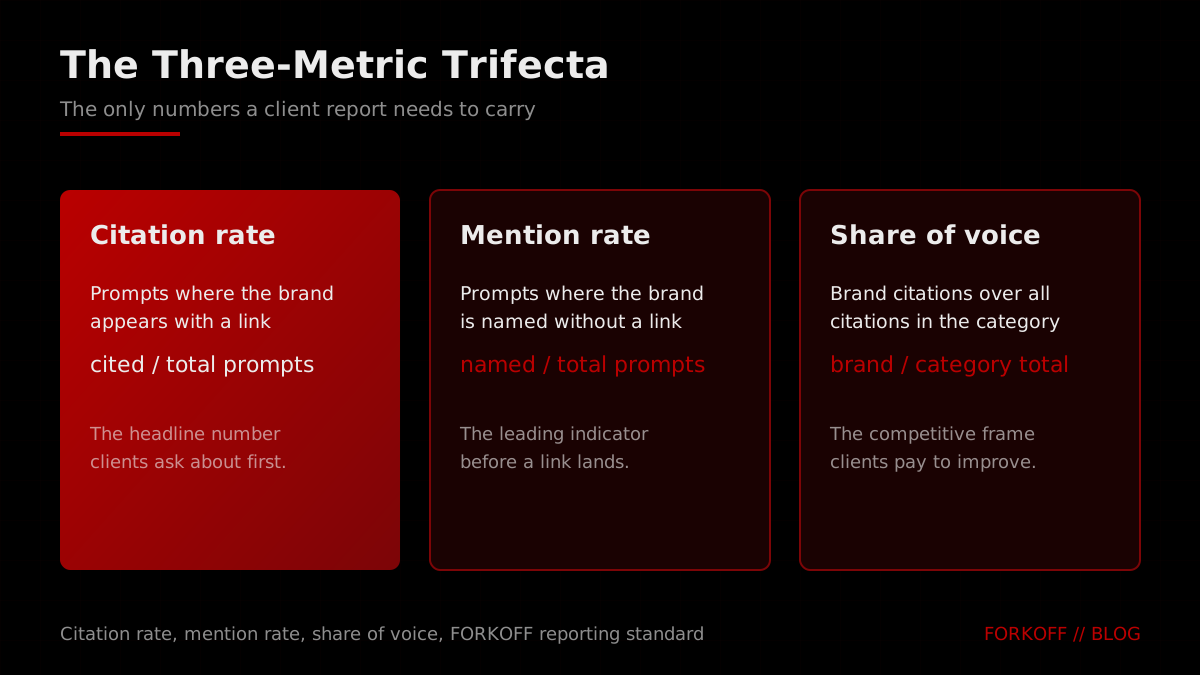
Citation rate is the share of prompts where the brand appears with a clickable link. Mention rate is the share where the brand is named without a link, which is the leading indicator that a link is coming. Share of voice is the brand's citations as a fraction of all citations in the category, which is the competitive frame the client actually pays to improve. Keep the definitions identical across every client so your agency speaks one language internally.
The three metrics every client AI citation report carries
| Metric | Definition | Formula | What it tells the client |
|---|---|---|---|
| Citation rate | Prompts where the brand appears with a clickable link | cited prompts / total prompts | Headline number, are we in the answer |
| Mention rate | Prompts where the brand is named without a link | named prompts / total prompts | Leading indicator before a link lands |
| Share of voice | Brand citations as a fraction of all category citations | brand citations / category citations | Competitive frame, who owns the category |
The audit also tells you where to spend. Map each missing citation back to a fixable cause: no answer capsule on the relevant page, stale content, thin schema, or no earned coverage on the query. That mapping is the bridge from diagnosis to the work order, and it is what separates a citation report from a citation program.
A practical tip on the raw log: record the exact citation alongside the verdict, not just the yes-or-no. When the brand is absent, note which competitor or which source the engine cited instead. That single column turns the audit from a scorecard into a target list. If the engine keeps citing a particular review platform for a comparison query, the work order is a placement on that platform, not another blog post. If it keeps citing a competitor's documentation, the work order is better-structured documentation on the client side. The agencies that win this work are the ones whose audit hands the content and outreach teams a specific, sourced instruction rather than a percentage that went down.
Run the first full audit before you quote the engagement, not after. A baseline gives you the honest scope, and it gives the client a number that makes the budget self-justifying. Walking into a pitch with "you are cited in four of forty buyer prompts and your closest competitor is cited in twenty-six" is a stronger open than any deck of generic AI-search statistics.
The answer capsule pattern
Of all the fixes the audit surfaces, the answer capsule has the best effort-to-result ratio. It is a two to three sentence direct answer to the query, placed in the first 200 words of the page, written so an engine can lift it verbatim. A technical SEO shared a clean before-and-after from running this across a top-20 page set.
Added answer capsules to our top 20 pages, a clean 200-word direct answer in the first fold. Citation rate on Perplexity went from about 8 percent to about 31 percent over six weeks. ChatGPT was slower, maybe 14 percent after ten weeks. The biggest jump was on queries where we had a clean definition the engine could pull verbatim.
Operator note200-word capsule in the first fold moved one client from 8 to 31 percent Perplexity citation rate in six weeks.
The capsule works because it removes ambiguity. When the engine needs a definition or a direct answer, a page that hands it one in clean prose beats a page that buries the answer under throat-clearing. Write the capsule to stand alone, lead with the concrete answer, and avoid the hedging that makes an engine reach for a competitor's cleaner sentence. A walkthrough of the broader signal set is worth showing a client who wants to see the mechanics rather than take the agency's word for it.
This Method Gets You Cited by ChatGPT, Perplexity & Google AI
Nico | AI Ranking
A walkthrough of the signals that get a brand cited across ChatGPT, Perplexity, and Google AI.
Authority signals that drive citations
The capsule earns the click once a buyer is already searching the brand. Earned coverage earns the citation that puts the brand in the answer before the buyer knows the brand. This is the part of the program that justifies a real budget, because it is the part the client cannot do alone with a content calendar.
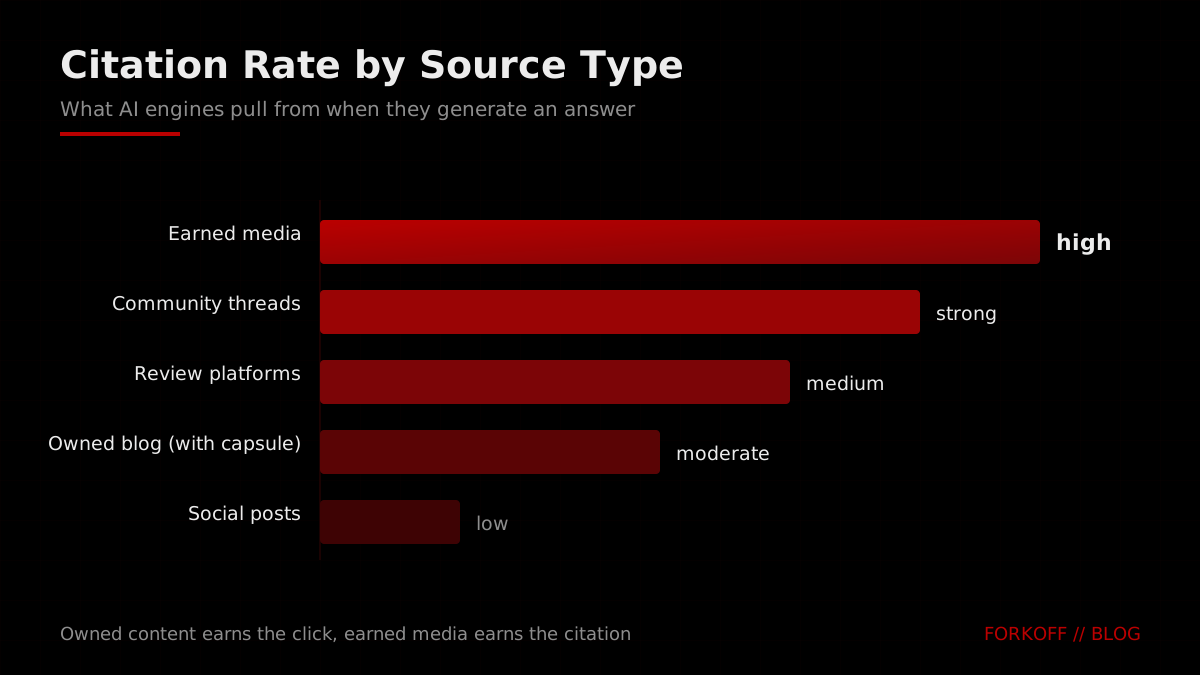
The hierarchy is consistent: earned media and independent coverage sit at the top of what engines pull, community discussion and review platforms in the strong middle, owned content with a capsule in the moderate band, and raw social posts near the bottom. A bootstrapped founder described the earned-media path in terms any agency can repeat to a client who wants to buy their way in.
It is not about paying ChatGPT. It is about being in the sources ChatGPT already trusts. We got three placements in reputable tech press in six months and our citation rate tripled. You cannot buy your way in. You have to earn coverage from sources it already knows.
The agency role here is to build the scaffolding, not to chase one placement. A structured web of authoritative content, executive thought leadership, and strategic media placements is what makes a client the default answer in a category over time. The LLM SEO service and the broader AI SEO services lane are where FORKOFF scopes the earned-coverage track alongside the on-page work.
Content freshness and citation decay
A page that wins a citation is not a finished asset. Engines favor recent content, so a page left untouched past 90 days drifts down the citation stack as competitors publish fresher material. This is why freshness is a recurring deliverable rather than a one-time fix, and it is the cleanest justification for an ongoing retainer rather than a project fee.
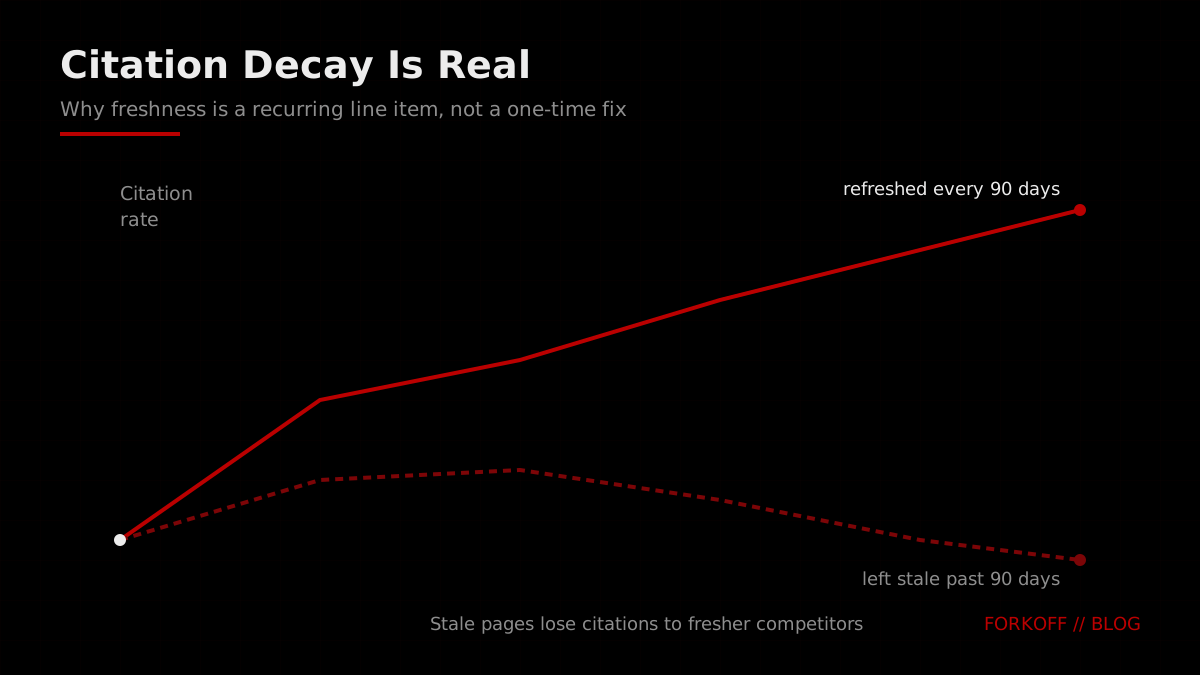
Build a freshness cadence into the engagement: a rolling schedule that revisits the highest-value cited pages before they age past the window, refreshes the data, updates the capsule, and re-stamps the modified date. Frame it to the client the way technical SEO maintenance is framed, as upkeep that protects an asset, not as net-new content. The answer engine optimization guide lays out the cadence in detail, and the answer engine optimization playbook carries the operator-grade version.
Citation decay turns freshness into a recurring line item
A page that wins citations is not a finished asset. Engines favor recent content, and a page left untouched past 90 days drifts down the citation stack as fresher competitors publish. That makes a freshness cadence a recurring deliverable rather than a one-time fix, and it is the cleanest way to justify an ongoing retainer rather than a project fee. The agencies that frame freshness as maintenance, the way technical SEO is framed as maintenance, keep the work renewing month over month.
Source: FORKOFF content cadence model, 2026
Technical signal stack and schema
Underneath the content work sits the machine-readability layer. Engines that cannot parse a page reliably will not cite it confidently. The technical track is the least glamorous part of the program and the one clients most often skip, which is exactly why it is leverage.
The baseline is Organization schema and a clean entity graph so the engine knows who the brand is, FAQPage schema on the pages that answer real buyer questions, and consistent structured data across the product catalog or service pages. Google's structured data reference documents the FAQ markup, and the broader schema vocabulary lives at schema.org's Organization type, its FAQPage type, and its Article type for editorial content. A companion post on schema markup for AEO carries the implementation detail an agency hands to a developer.
The technical track is also where you catch the silent failures: a page that renders for users but blocks crawlers, inconsistent canonical signals, or a JavaScript-rendered answer the engine never sees. A short audit on these before the content work starts saves a quarter of chasing citations on pages the engine cannot read.
There is a second technical lever that agencies routinely miss: making the answer extractable, not just present. An engine that wants a definition will reach for the page that hands it a clean one in plain prose with clear surrounding context. A page where the answer is split across a hero image, a tooltip, and a paragraph three scrolls down is harder to pull from than a page with a single labeled capsule. The fix is structural rather than additive. You are not writing more, you are arranging the existing answer so a parser can lift it without guessing. Headings that mirror real buyer questions, short self-contained paragraphs, and a consistent schema wrapper do most of the work. This is the same discipline that wins featured snippets in classic search, redirected at a generative surface, which is why agencies with a strong technical SEO bench ramp into citation work faster than content-only shops.
Setting client benchmarks
A number without a comparison is not a benchmark. The audit gives you the client's citation rate, mention rate, and share of voice, but the client's question is whether those numbers are good. Answer it by always reporting against three named competitors in the same category, run through the identical prompt set.
The three-competitor frame does two things. It turns an abstract percentage into a competitive position the client's leadership understands instantly, and it gives the agency a clear target: close the gap to the category leader, or extend the lead. When a client sees they are cited in three of forty prompts while a competitor is cited in twenty-eight, the gap is concrete and the budget conversation gets easier. Set the benchmark at the start of the engagement, freeze the competitor set for the quarter, and revisit it only at the business review so the trend stays honest.
Pick the three competitors with the client, not for them. The competitor a founder fears is not always the one the engine cites, and that discrepancy is itself a finding worth presenting. Sometimes the brand the engine treats as the category default is a player the client had dismissed, and seeing that in the audit reframes the whole conversation. Lock the set early so the denominator does not drift, and resist the urge to swap competitors mid-quarter when the numbers are unflattering. A benchmark is only useful if it stays stable long enough to show a trend, and a moving competitor set is the fastest way to make a report that no one trusts. If the client genuinely enters a new competitive set, note the change explicitly in the report and start a fresh baseline rather than quietly editing the old one.
Choosing the citation tool stack
Tools are a layer, not the strategy, and the right tool tier depends on the prompt volume the engagement requires and how many brands you are tracking simultaneously. For a single-domain client, an entry-tier monitor covering a few hundred prompts per week is enough. For a multi-brand retainer, a mid-tier platform with competitor share-of-voice benchmarking earns its cost. Buying the enterprise tier for a single-domain client because the demo impressed is the most common overspend on this side of the program.
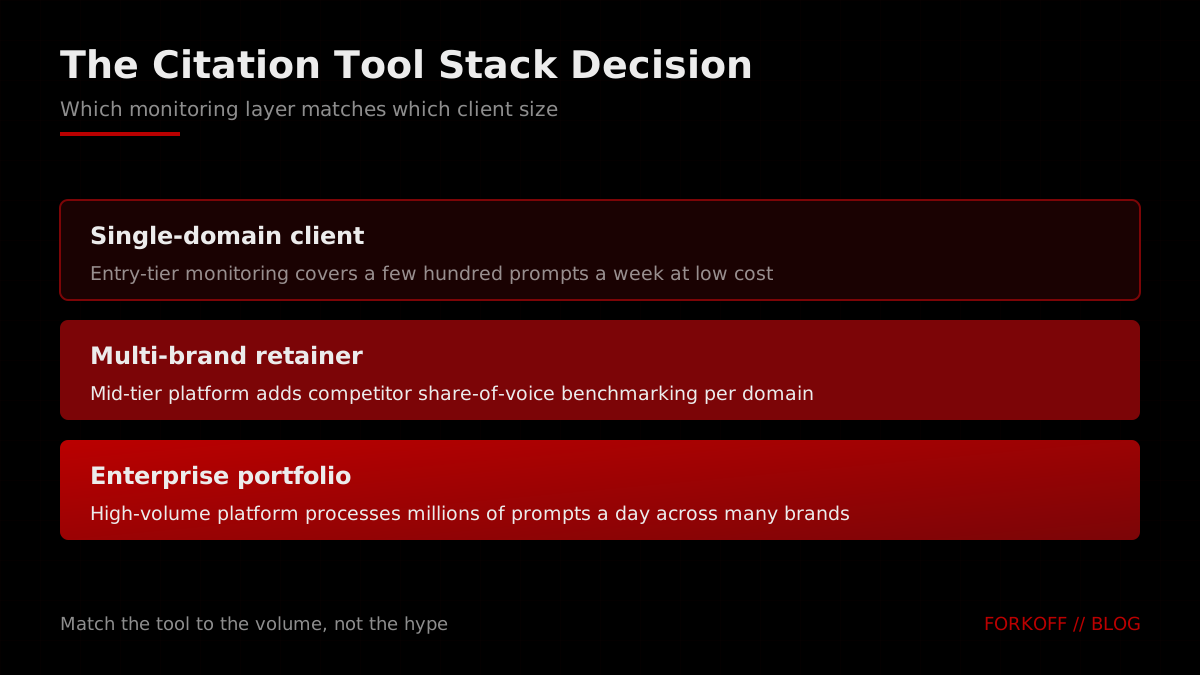
For a single-domain client, an entry-tier monitor covering a few hundred prompts a week is plenty. Tools in this band, such as Otterly.ai, handle low-volume single-domain tracking. For a multi-brand retainer, a mid-tier platform that adds competitor share-of-voice benchmarking earns its cost, with options like the Semrush AI toolkit and Ahrefs Brand Radar in that band. For an enterprise portfolio, a high-volume platform such as Profound or BrightEdge processes the prompt counts a large account demands.
How the engagement is scoped and priced by client size
| Client tier | Topic clusters | Prompts per week | Monitoring layer |
|---|---|---|---|
| Single domain | 1 to 2 | 60 to 120 | Entry-tier prompt monitor |
| Mid-market | 3 to 5 | 180 to 300 | Competitor share-of-voice platform |
| Enterprise portfolio | 6 plus across brands | Thousands | High-volume multi-brand platform |
The mistake is buying the enterprise tier for a single-domain client because the demo was impressive. Match the spend to the volume. The tools comparison post covers where each platform fits, and the free AEO checker, which runs the GEO audit and the AEO checks together, is a first read before you commit a client to a paid subscription.
Citation monitoring cadence
Monitoring is only useful if it produces the right signal at the right interval to the right person. Over-report and the account team drowns. Under-report and the client feels ignored. The cadence below is what works across most retainers.
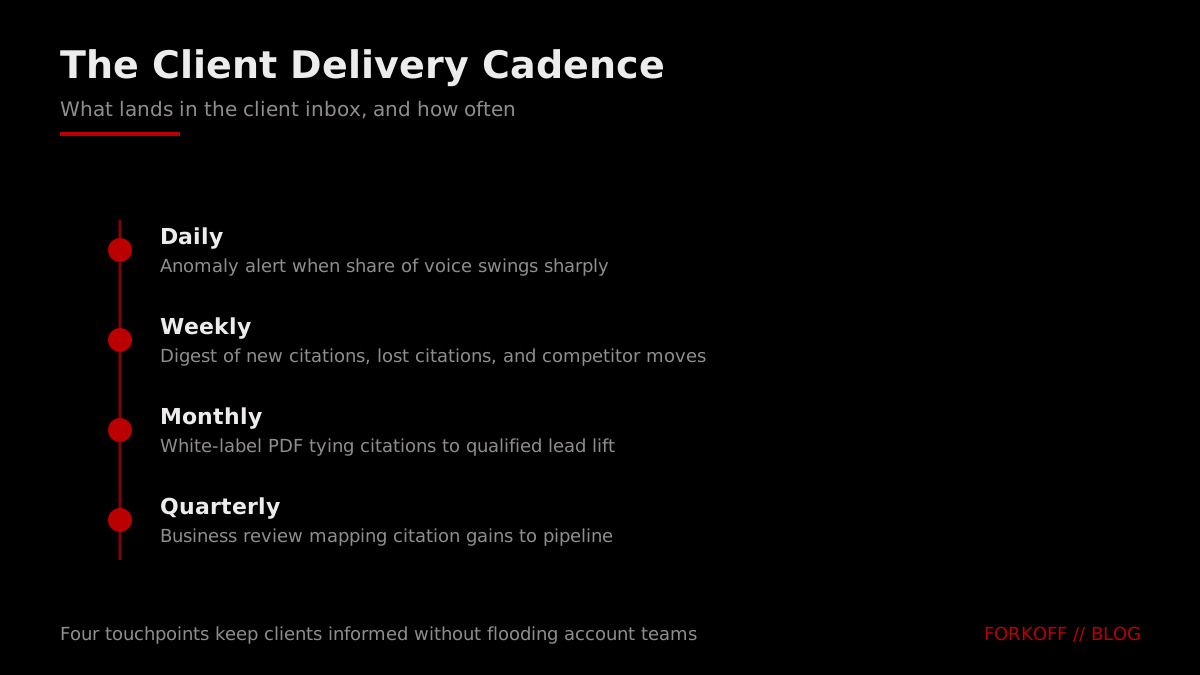
A daily anomaly alert fires only when share of voice swings sharply, so the account team acts on real movement rather than noise. A weekly digest summarizes new citations won, prior citations lost, and competitor moves, which is enough for the working relationship. The monthly white-label PDF is the formal deliverable that ties citations to qualified lead lift. The quarterly business review maps citation gains to pipeline and resets the plan. Four touchpoints, each scoped to its audience.
Operator note11 percent domain overlap between ChatGPT and Perplexity. Two tracks, two content calendars, two reports.
Packaging the white-label report
The monthly report is the artifact that renews the retainer, so treat it as a sales asset, not a data dump. Keep it to one page of scannable charts that a client executive can absorb in two minutes and forward to their board.
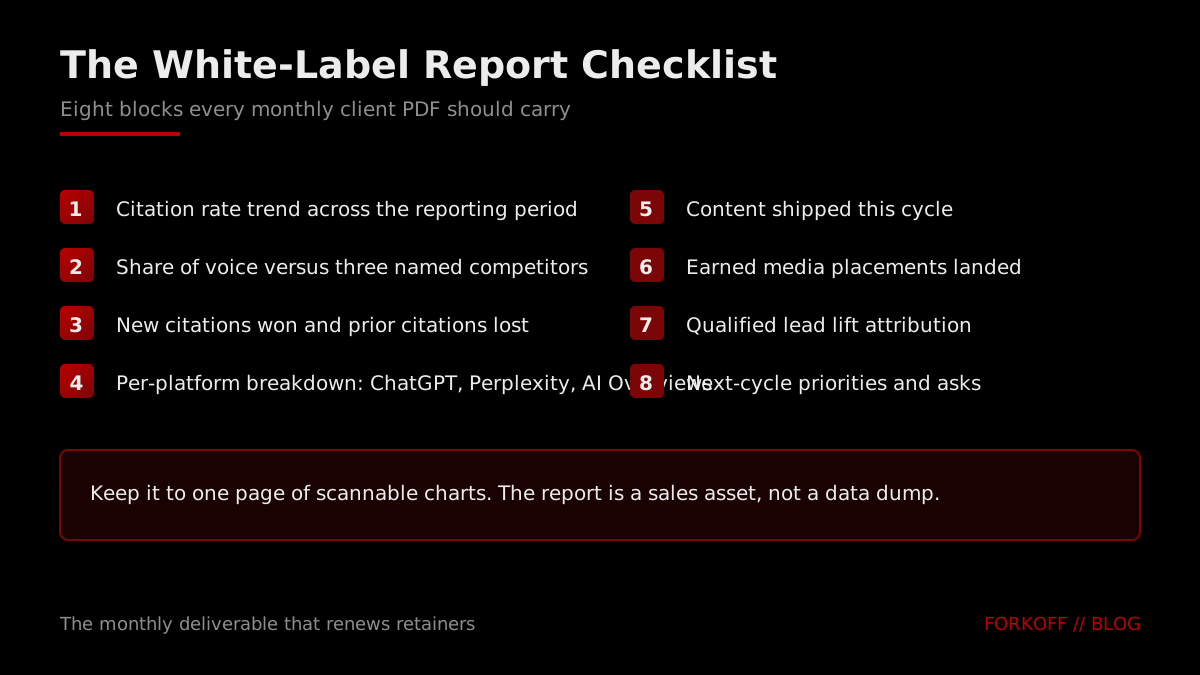
The eight blocks that belong in it: citation-rate trend over the period, share of voice against the three named competitors, new and lost citations, a per-platform breakdown across ChatGPT, Perplexity, and AI Overviews, the content shipped this cycle, earned media landed, qualified lead lift attribution, and next-cycle priorities. Brand it to the client, lead with the share-of-voice chart, and let the data carry the renewal conversation. One agency owner described exactly how that section drove retainer upgrades.
We added AI citation monitoring to our retainers in Q1 and framed it as AI Share of Voice in the report. Clients immediately understood. Two upgraded their retainers specifically for this. The tools cost us 30 to 100 dollars a month per client and we are billing an extra 500 to 1,500 for the section. Margins are good.
Operator noteThe monthly PDF is one page of charts. Two clients upgraded retainers off the share-of-voice section alone., agency owner, r/agency
This is also where the commercial case for the whole program lands. Agencies are seeing real client pull for this work, and the threads where owners compare notes show it is no longer an early-adopter curiosity.
Any agencies seeing demand for GEO from clients?
An agency owner asks peers whether clients are actively requesting generative engine optimization work, and the replies map out how shops are packaging and pricing AI citation services as a new retainer line.
Positioning and selling the service line
A well-built citation program still has to be sold, and the framing matters more than most agency principals expect. Lead with the client's own question: "are we showing up in ChatGPT?" Present the citation report as the instrument that answers it with a number. Anchor the value in share of voice because it is the metric leadership grasps fastest, and show the loop: audit, benchmark, fix, earn, report. Jeff Sauer's walkthrough of selling answer engine optimization as a service line is a useful reference for the positioning conversation an agency principal has internally.
Answer Engine Optimization Is the New SEO, Here's How to Sell It
Jeff Sauer - Service Stacking
Jeff Sauer on positioning answer engine optimization as a sellable agency service line.
Lead with the client's own question, "are we in the answer," and present the citation report as the instrument that answers it. Anchor the value in share of voice, because it is the metric leadership grasps fastest. Then show the loop: audit, benchmark, fix, earn, report. The clients who move budget into this often move it from somewhere else, and the agency that can show why citation building beats the prior line item wins the reallocation.
client wants to move backlink budget into citation building, is this real?
A practitioner shares that a client wants to reallocate backlink budget toward AI citation building, prompting a debate on whether citation work is a durable discipline or a rebranded version of existing SEO.
The objection you will hear is whether this is a real discipline or a rebranded version of work the client already buys. The honest answer is that it overlaps with SEO at the technical base and diverges sharply at the earned-media and platform-divergence layers. A clear explanation of why most B2B brands are invisible to answer engines, and what to fix first, helps a prospect see the gap in their current program.
What Is AEO? (And Why Most B2B SaaS Are Invisible)
Liam Dunne
Why most B2B SaaS brands are invisible to answer engines, and what to fix first.
How FORKOFF runs the citation program
At FORKOFF we run this loop for AI-native founders, and the engagement maps to the phases above. We build the prompt set against the client's real buyer journey, run the weekly cross-platform audit, and benchmark against the three competitors that matter to the client's category. We documented one full citation lab rerun in our GEO citation lab post, and the share-of-AI-citations measurement post carries the metric math we report against.
The fixes follow the audit, not a template. Where the gap is on-page, we ship capsules and schema. Where it is authority, we build the earned-coverage scaffolding. Where it is freshness, we put the highest-value pages on a 90-day cadence. This work sits alongside our work for AI startups and SaaS companies, and the citation program is the same engine pointed at whichever surface the client's buyers actually use.
For the vertical applications, the podcast AEO citation strategy shows the channel-specific version, and the B2B AEO checklist sequences the first 90 days of an engagement. If you are comparing providers, the best AEO agency and best GEO agency comparisons lay out the field, and the FORKOFF vs Rankstar head-to-head breaks down a published citation methodology against a bundled multi-service SEO retainer.
The reporting layer is where we keep the engagement honest with the client and with ourselves. Every number in the monthly PDF traces back to the prompt log, every cited and lost citation is sourced, and the lead-lift attribution is tied to the client's own pipeline data rather than to a vanity proxy. That discipline is slower to set up than a tool dashboard screenshot, and it is the reason the work renews. A client who can see exactly which buyer prompts moved, which competitor lost ground, and which placement drove the change does not treat the line item as discretionary. The agencies that get churned on this work are the ones who reported a tool's dashboard and called it a deliverable. The ones who keep it built a report the client could hand to their board.
The verdict: citations are an operating discipline, not a content trick
The agencies winning this work are not the ones with the cleverest single tactic. They are the ones who turned the client's question into a repeatable loop with a number at every stage and a deliverable at the end of every cycle. Audit prompt coverage, benchmark against named competitors on citation rate and share of voice, ship capsules and schema and earned coverage in the order the audit dictates, keep the cited pages fresh past the 90-day window, and report it in a one-page white-label PDF that ties citations to lead lift.
The platform divergence is the discipline's hardest constraint and its clearest moat: with only 11 percent of cited domains shared between ChatGPT and Perplexity, an agency that runs two tracks beats one that runs a single content calendar, every time. The freshness decay is what makes the work recurring rather than a project, which is what makes it a retainer rather than a one-off. Build the loop once, run it on every account, and the citation report becomes the thing clients renew for. When you are ready to stand it up on a real client, talk to FORKOFF and we will run the first audit with you.